Model icon
deepseek-v4-flash
Chat
Model:
DeepSeek V4 Flash is a fast, economical DeepSeek V4 API model with 1M-context chat, 284B total parameters, and 13B active parameters.
Chat

This Playground is for demo purposes. Data is only valid in the current window and will be cleared on refresh.

Type a message...

Configuration
1.0
1.0
Pricing details

Transparent pricing with no hidden fees. Pay as you go.

DeepSeekdeepseek-v4-flash
Input tokens
PoYo price
$0.112/1M tokens
22.8 credits
Official price
$0.140/1M tokens
Official
You save
20%
DeepSeekdeepseek-v4-flash
Output tokens
PoYo price
$0.224/1M tokens
45.6 credits
Official price
$0.280/1M tokens
Official
You save
20%

* Actual fees are based on the final output.

Introduction

Complete guide to using DeepSeek V4 Flash API

DeepSeek V4 Flash API

DeepSeek V4 Flash is a fast, economical DeepSeek V4 API model with 1M-context chat, 284B total parameters, and 13B active parameters.

DeepSeek V4 model access

01

DeepSeek V4 Flash

Use model ID deepseek-v4-flash. DeepSeek documents it as a fast, economical V4 API model with 284B total parameters and 13B active parameters.
View Documentation

DeepSeek V4 API highlights

DeepSeek V4 Preview is officially available with 1M context and separate Flash and Pro profiles.

01

284B total / 13B active MoE profile

DeepSeek V4 uses a mixture-of-experts profile. Official docs list DeepSeek V4 Flash at 284B total / 13B active, giving teams a clear separation between the efficient Flash route and the stronger Pro route.

  • 284B total / 13B active
  • Optimized for fast, economical chat and simple agent workloads
  • Model ID: deepseek-v4-flash
DeepSeek V4 Flash official specification

02

Flash benchmark profile for efficient production traffic

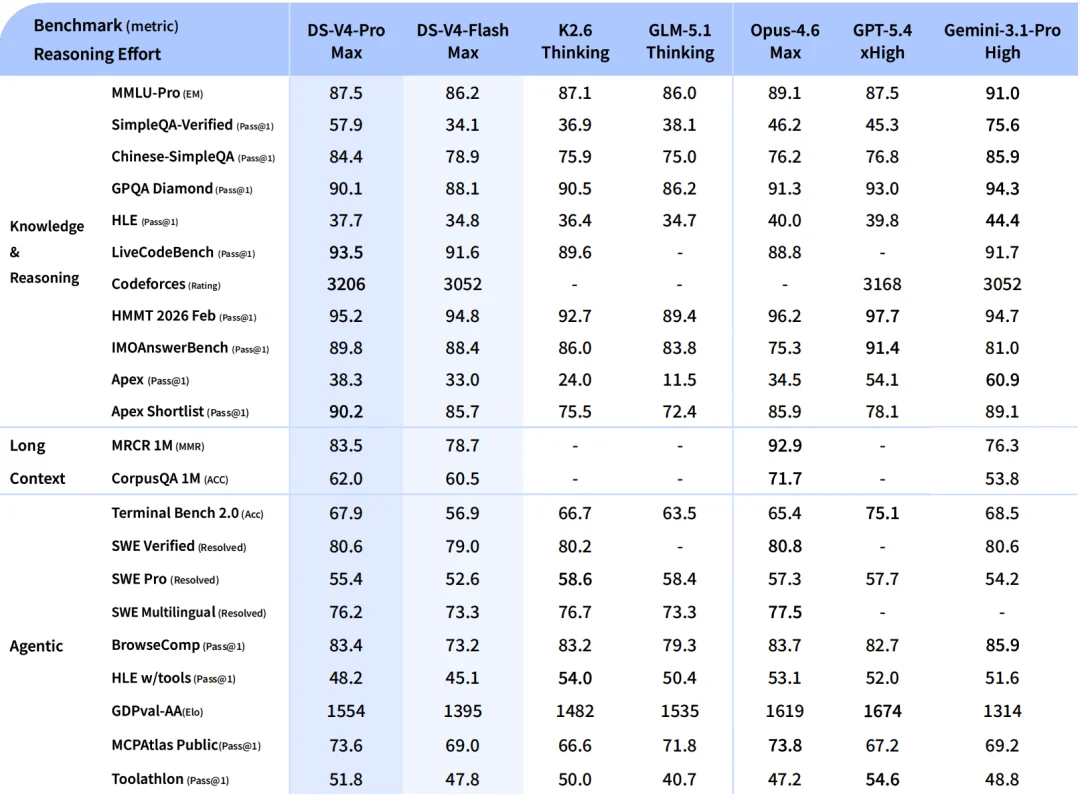
DeepSeek describes V4 Flash as closely approaching V4 Pro reasoning, matching Pro on simple agent tasks, and using a smaller active profile for faster response times and lower API cost.

  • Good default for high-volume chat traffic
  • Useful when latency and cost matter
  • Can be paired with Pro for escalation
DeepSeek V4 Flash benchmark chart

03

1M context for long conversations and documents

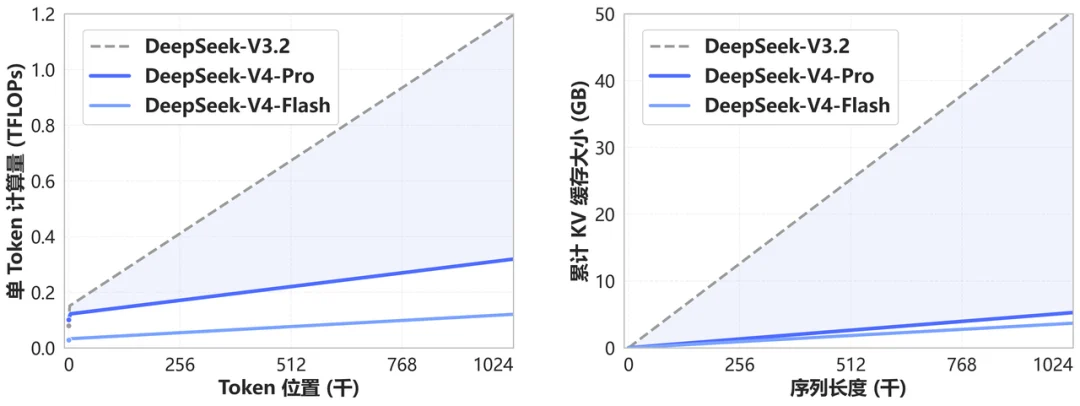
The official DeepSeek release notes state that 1M context is the default across official DeepSeek services. This is useful for long chats, repository-scale coding context, large documents, and multi-step agent memory.

  • 1M context stated in official release notes
  • Long document and repository context
  • Reduced chunking for agent workflows
DeepSeek V4 context efficiency

04

Thinking and non-thinking modes

DeepSeek documents dual modes for the V4 API family. Use non-thinking for faster direct answers and thinking mode for tasks where explicit reasoning effort improves quality.

  • Thinking mode for harder reasoning
  • Non-thinking mode for lower latency
  • Fits chat, coding, and agent routing
DeepSeek V4 agent example

Best use cases

01

High-volume chat assistants

Route common assistant, support, and Q&A traffic to the economical Flash profile.

02

Fast coding help

Use Flash for code explanations, simple edits, test ideas, and quick debugging loops.

03

Long-document Q&A

Use 1M context for large documents and knowledge packets without aggressive chunking.

04

Agent first pass

Let Flash handle simple planning and tool-use paths before escalating harder work to Pro.

DeepSeek V4 Flash vs DeepSeek V4 Pro

Both Model IDs come from the same DeepSeek V4 Preview API family. Choose Flash for efficient traffic and Pro for harder reasoning, coding, and agent work.

FeatureDeepSeek V4 FlashDeepSeek V4 Pro
Model IDdeepseek-v4-flashdeepseek-v4-pro
Total / active parameters284B / 13B1.6T / 49B
PositioningFast, efficient, economicalStronger reasoning, coding, agents
Context window1M context1M context
ModesThinking / Non-ThinkingThinking / Non-Thinking
Pricing22.8 input / 45.6 output credits per 1M tokens68.4 input / 136.8 output credits per 1M tokens

Sources: DeepSeek official V4 Preview release. Official source: https://api-docs.deepseek.com/news/news260424

How to use the API

Create a PoYo API key
Get API Key

Set the model ID
Use deepseek-v4-flash as the model ID in your request.

Open API docs
View API docs

API pricing

ModelInputOutput
DeepSeek V4 Flash$0.112 / 1M tokens
22.8 credits
$0.224 / 1M tokens
45.6 credits

FAQ

What model ID should I use?

Use deepseek-v4-flash.

Does it support 1M context?

Yes. DeepSeek official release notes state that both V4 Flash and V4 Pro support 1M context.