





01
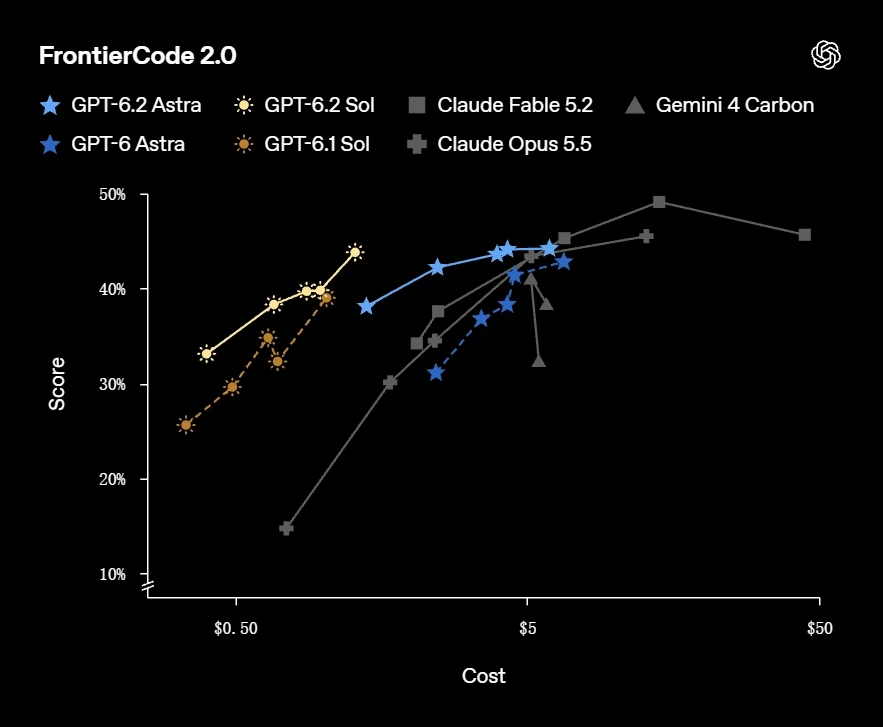
Coding Within 0.5 Points of Astra at One-Fifth the Cost
A code change only helps when it meets the standard a maintainer would merge. Cognition's FrontierCode 2.0 tests exactly that on real codebases. OpenAI reports that GPT-6.2 Sol comes within 0.5 points of GPT-6.2 Astra on this benchmark at about one-fifth the cost, with both models at max reasoning effort, so teams can apply coding quality close to Astra's across many more tasks.
- Make changes to real, existing codebases
- Target maintainers' standards for merging
- Run more coding tasks within the same budget